Hi, I’m Vishnu. I document hands-on experiments with Kubernetes, DevOps, GPUs, and local models. About me →
Latest notes
oMLX vs Ollama vs vMLX vs MLX-LM: Local LLMs on Apple Silicon
My local LLM picks for Apple Silicon: oMLX first, Ollama second, vMLX third, and official MLX-LM fourth. Setup commands and the benefits of each.
AI and LLM Glossary: Common Terms in Plain English
A beginner-friendly AI and LLM glossary with short definitions, everyday examples, and a clickable table of contents for every term.
Why vLLM Is Dominating the AI Inference Market
How PagedAttention, continuous batching, hardware portability, and an open ecosystem made vLLM the default engine for high-throughput LLM serving.
What the heck is an AI Agent?
A practical explanation of agentic AI, agent harnesses, tool loops, context growth, and why agents cost more to run.
What Happens When You Ask an LLM a Question
My visual notes on how LLMs work: tokens, parameters, attention, reasoning, KV cache, quantization, and serving models on GPUs.
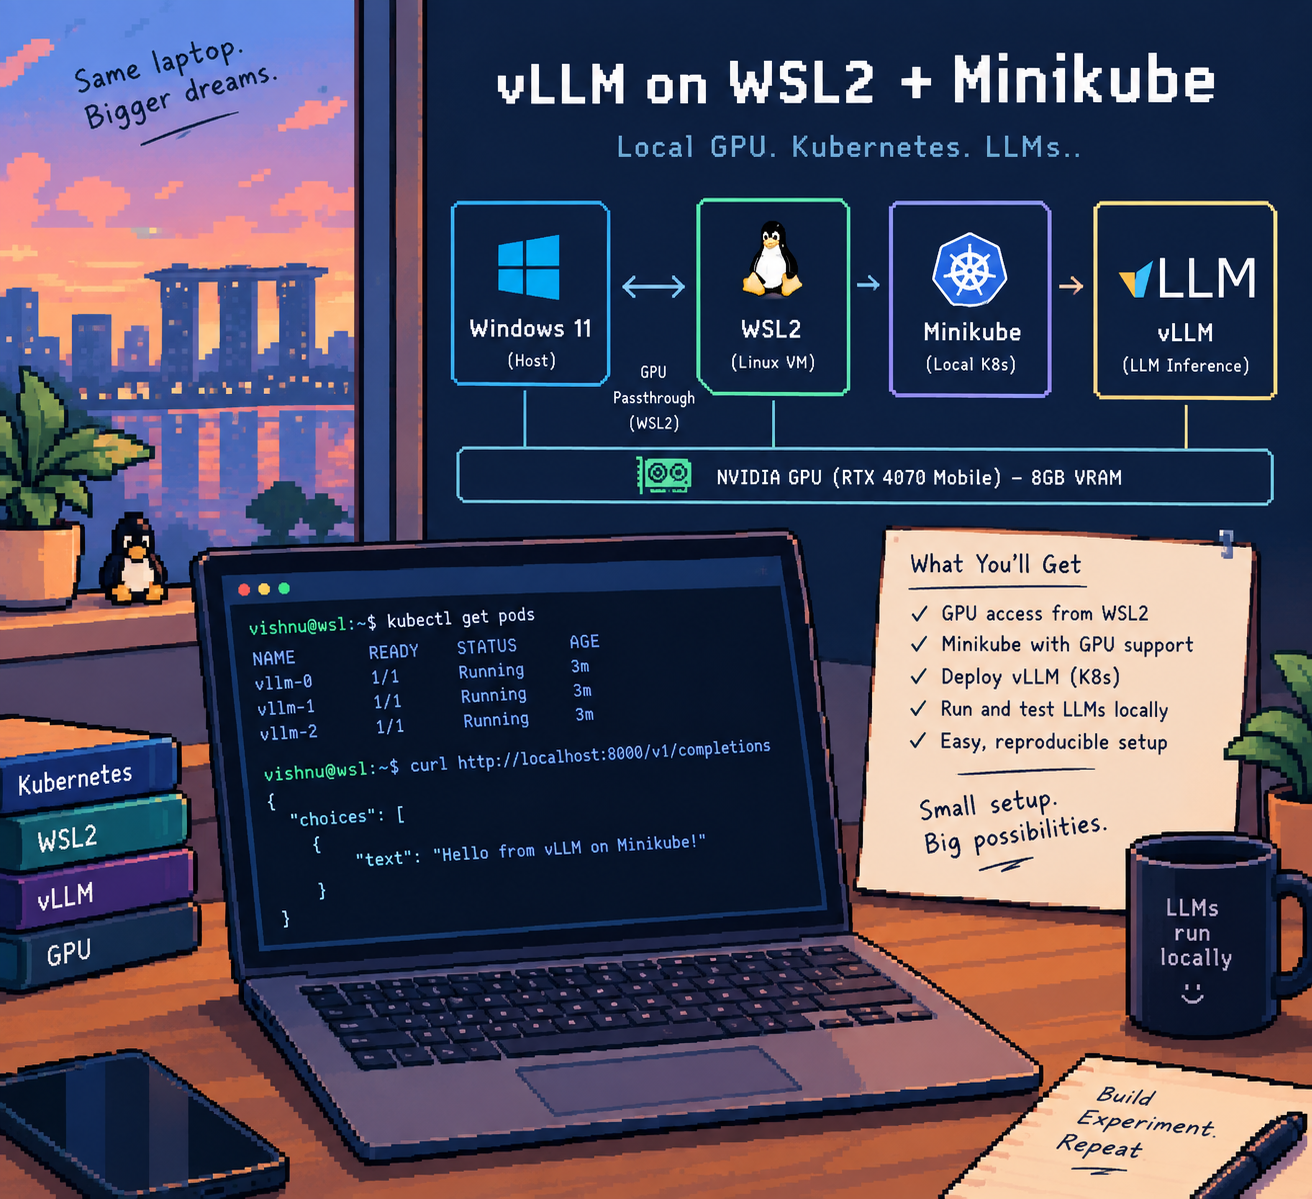
Run vLLM on Kubernetes with Minikube, WSL2 and NVIDIA GPU
A practical guide to running vLLM on Kubernetes in WSL2 with Minikube, configuring NVIDIA GPU passthrough, and serving an OpenAI-compatible API.
Running a 35B MoE Model on an 8 GB Laptop GPU: Testing FreeToken
Testing FreeToken on an RTX 4070 Laptop GPU: running Qwen 3.6 35B-A3B NVFP4 across 8 GB VRAM and 32 GB RAM with hierarchical memory offloading.
Kubernetes is Adding a K to YAML: Why KYAML Makes Sense
Kubernetes 1.37 makes KYAML stable: how flow style eliminates silent type coercion, removes load-bearing indentation, and how to try it.
Running llama.cpp on a 32 GB MacBook Air: A Direct Comparison with Ollama
Compile llama.cpp with Metal support on Apple Silicon, serve local GGUF models, and benchmark prompt eval and generation speeds head-to-head against Ollama.
Running Ollama on a 32 GB MacBook Air: A Practical First Setup
Install Ollama, pull and run local models, and call the local API on a 32 GB Apple-silicon MacBook Air.