Kubernetes GPU Platform Engineering: From nvidia-smi to NCCL
A simple, layered guide to GPUs on Kubernetes: GPU Operator, NUMA and PCIe, RDMA, SR-IOV and Multus, NVLink and NCCL, with a troubleshooting question for every layer.
$ ls -t ./notes
A simple, layered guide to GPUs on Kubernetes: GPU Operator, NUMA and PCIe, RDMA, SR-IOV and Multus, NVLink and NCCL, with a troubleshooting question for every layer.
A Windows walkthrough of Hermes Agent connected to LM Studio Bionic with Gemma 4 E4B: local inference, custom endpoint settings, tool use, and the checks that confirm it works.
My early-access look at TypeSafe’s Jev: Noul, Choice, and Score in the playground, the coding-agent skill, and what the performance claims do and do not establish.
Karmada's CNCF graduation, its multi-cluster architecture, and practical YAML for placement, replica splitting, overrides, and failover.
An example-driven guide to LMCache: repeated prefill, KV cache reuse, CPU offloading, multi-replica serving, and where caching actually helps.
My local LLM picks for Apple Silicon: oMLX first, Ollama second, vMLX third, and official MLX-LM fourth. Setup commands and the benefits of each.
A beginner-friendly AI and LLM glossary with short definitions, everyday examples, and a clickable table of contents for every term.
How PagedAttention, continuous batching, hardware portability, and an open ecosystem made vLLM the default engine for high-throughput LLM serving.
A practical explanation of agentic AI, agent harnesses, tool loops, context growth, and why agents cost more to run.
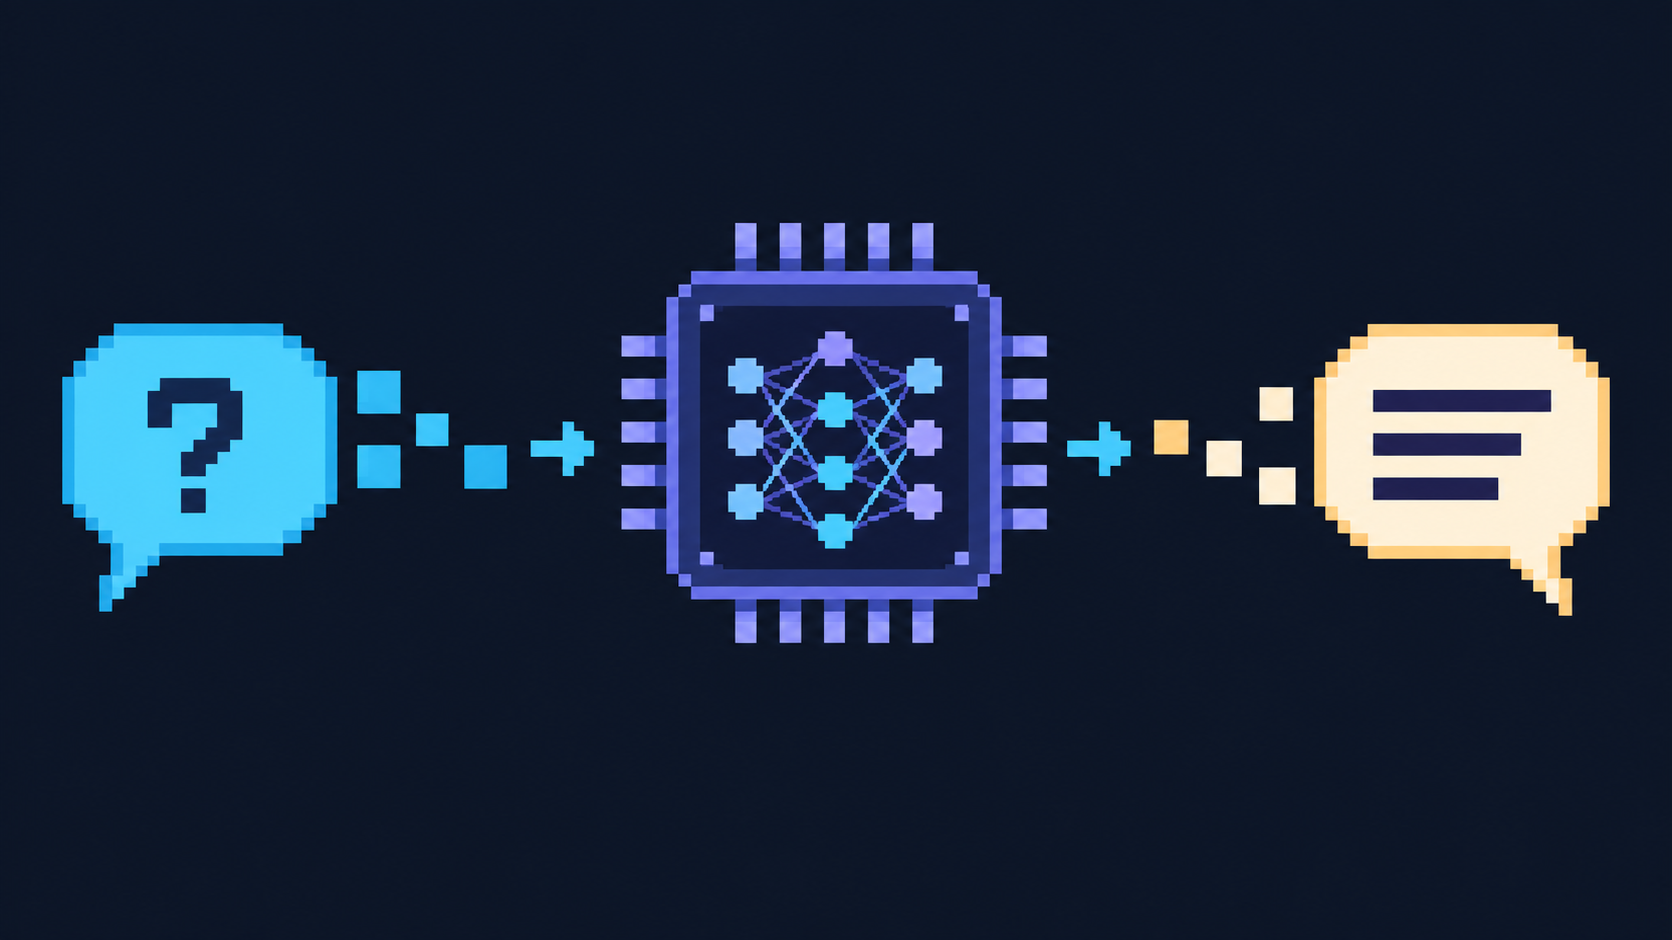
My visual notes on how LLMs work: tokens, parameters, attention, reasoning, KV cache, quantization, and serving models on GPUs.