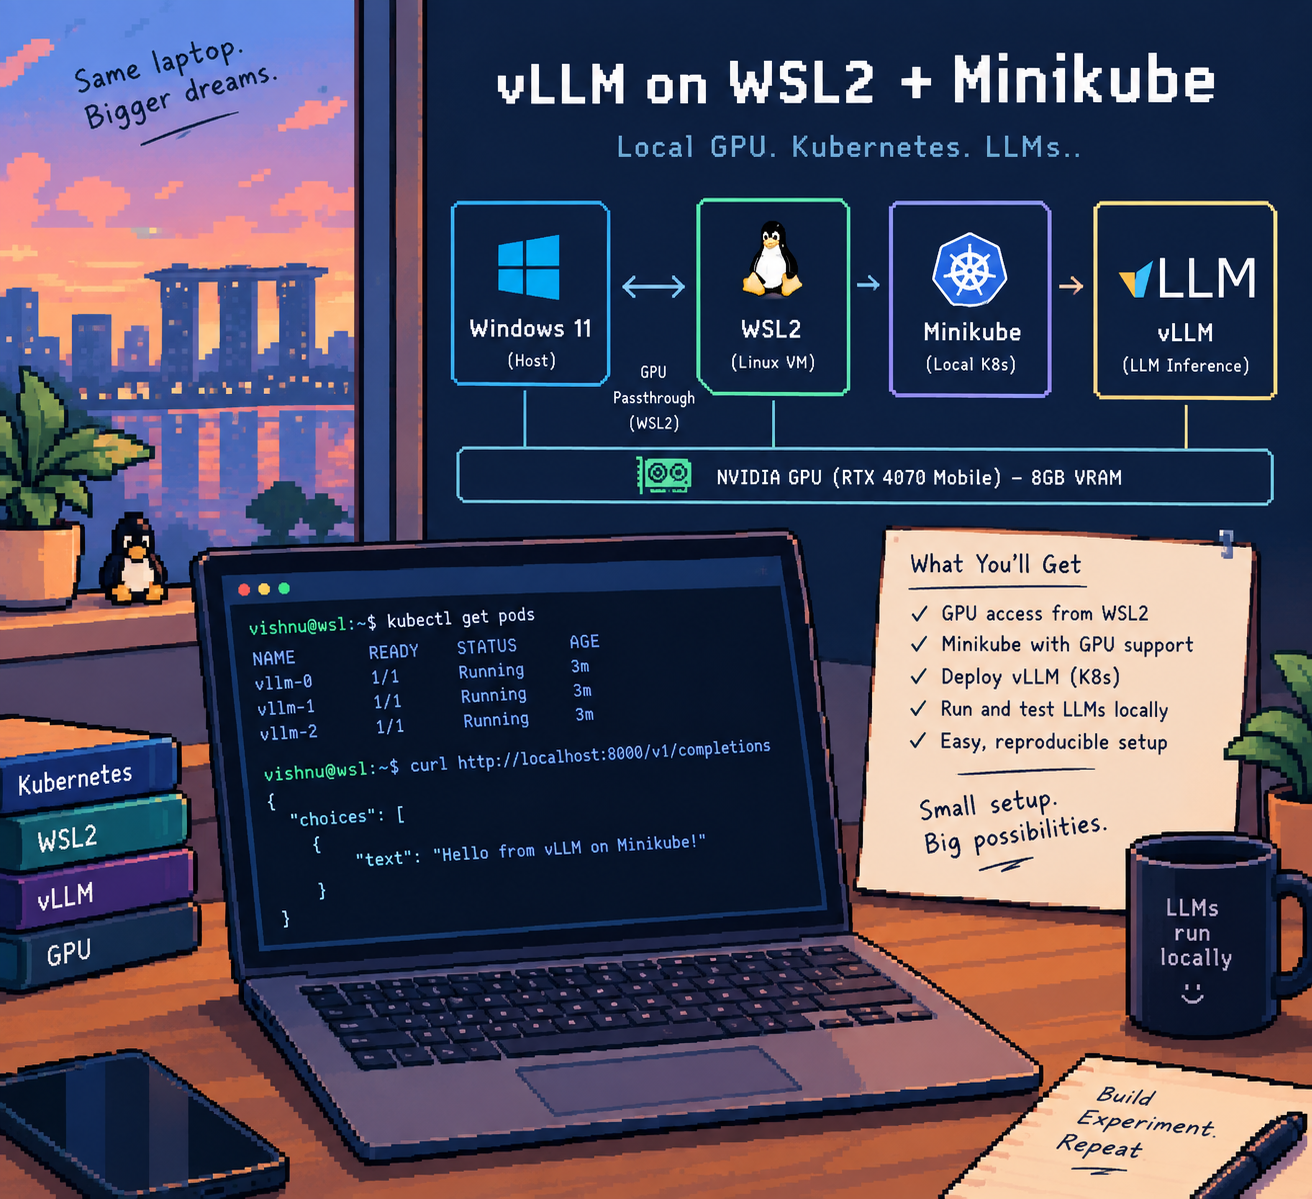
Run vLLM on Kubernetes with Minikube, WSL2 and NVIDIA GPU
A practical guide to running vLLM on Kubernetes in WSL2 with Minikube, configuring NVIDIA GPU passthrough, and serving an OpenAI-compatible API.
$ ls -t ./notes
A practical guide to running vLLM on Kubernetes in WSL2 with Minikube, configuring NVIDIA GPU passthrough, and serving an OpenAI-compatible API.
Testing FreeToken on an RTX 4070 Laptop GPU: running Qwen 3.6 35B-A3B NVFP4 across 8 GB VRAM and 32 GB RAM with hierarchical memory offloading.
Kubernetes 1.37 makes KYAML stable: how flow style eliminates silent type coercion, removes load-bearing indentation, and how to try it.
Compile llama.cpp with Metal support on Apple Silicon, serve local GGUF models, and benchmark prompt eval and generation speeds head-to-head against Ollama.
Install Ollama, pull and run local models, and call the local API on a 32 GB Apple-silicon MacBook Air.
My notes on Kubernetes v1.37: native HPA scale-to-zero, tracking unused PVCs, ClusterTrustBundles, and etcd streaming.
A quick intro to vishctl, my background in Kubernetes and AI infra, and why this blog exists.