Why LMCache Exists: Stop Making GPUs Read the Same Context Again
An example-driven guide to LMCache: repeated prefill, KV cache reuse, CPU offloading, multi-replica serving, and where caching actually helps.
$ vishctl get notes
An example-driven guide to LMCache: repeated prefill, KV cache reuse, CPU offloading, multi-replica serving, and where caching actually helps.
My local LLM picks for Apple Silicon: oMLX first, Ollama second, vMLX third, and official MLX-LM fourth. Setup commands and the benefits of each.
A beginner-friendly AI and LLM glossary with short definitions, everyday examples, and a clickable table of contents for every term.
How PagedAttention, continuous batching, hardware portability, and an open ecosystem made vLLM the default engine for high-throughput LLM serving.
A practical explanation of agentic AI, agent harnesses, tool loops, context growth, and why agents cost more to run.
My visual notes on how LLMs work: tokens, parameters, attention, reasoning, KV cache, quantization, and serving models on GPUs.
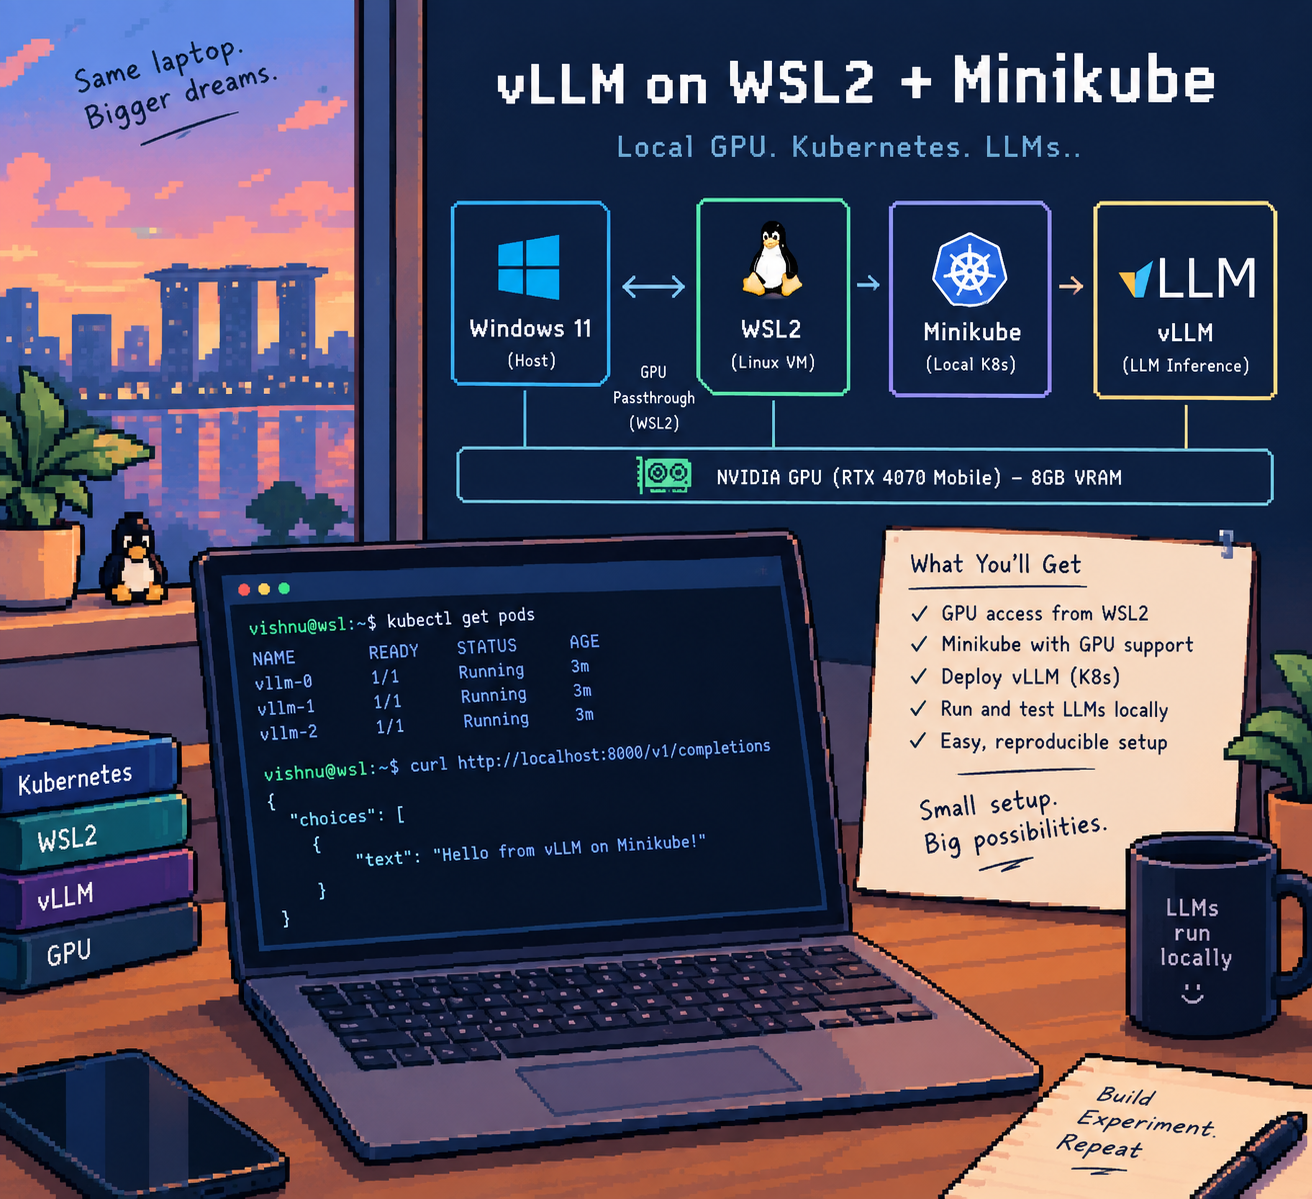
A practical guide to running vLLM on Kubernetes in WSL2 with Minikube, configuring NVIDIA GPU passthrough, and serving an OpenAI-compatible API.
Testing FreeToken on an RTX 4070 Laptop GPU: running Qwen 3.6 35B-A3B NVFP4 across 8 GB VRAM and 32 GB RAM with hierarchical memory offloading.
Kubernetes 1.37 makes KYAML stable: how flow style eliminates silent type coercion, removes load-bearing indentation, and how to try it.
Compile llama.cpp with Metal support on Apple Silicon, serve local GGUF models, and benchmark prompt eval and generation speeds head-to-head against Ollama.