Pixel art laptop projecting a holographic GPU cluster of amber wireframe cards, with a router tower sending request cubes to them and the brightest path going to the card that holds matching cache cubes

No GPU? Simulate One: vLLM, llm-d, and 16 Fake H100s on a Laptop

A hands-on lab for learning GPU scheduling and LLM routing without a GPU: kind, fake-gpu-operator, llm-d-inference-sim, and the llm-d router, with real screenshots and benchmark numbers.
Pixel art Kubernetes GPU cluster with two servers, cyan GPU interconnects, and a violet network fabric

Kubernetes GPU Platform Engineering: From nvidia-smi to NCCL

A simple, layered guide to GPUs on Kubernetes: GPU Operator, NUMA and PCIe, RDMA, SR-IOV and Multus, NVLink and NCCL, with a troubleshooting question for every layer.

Pixel art showing a question becoming tokens, passing through a neural-network chip, and emerging as an answer

What Happens When You Ask an LLM a Question

My visual notes on how LLMs work: tokens, parameters, attention, reasoning, KV cache, quantization, and serving models on GPUs.

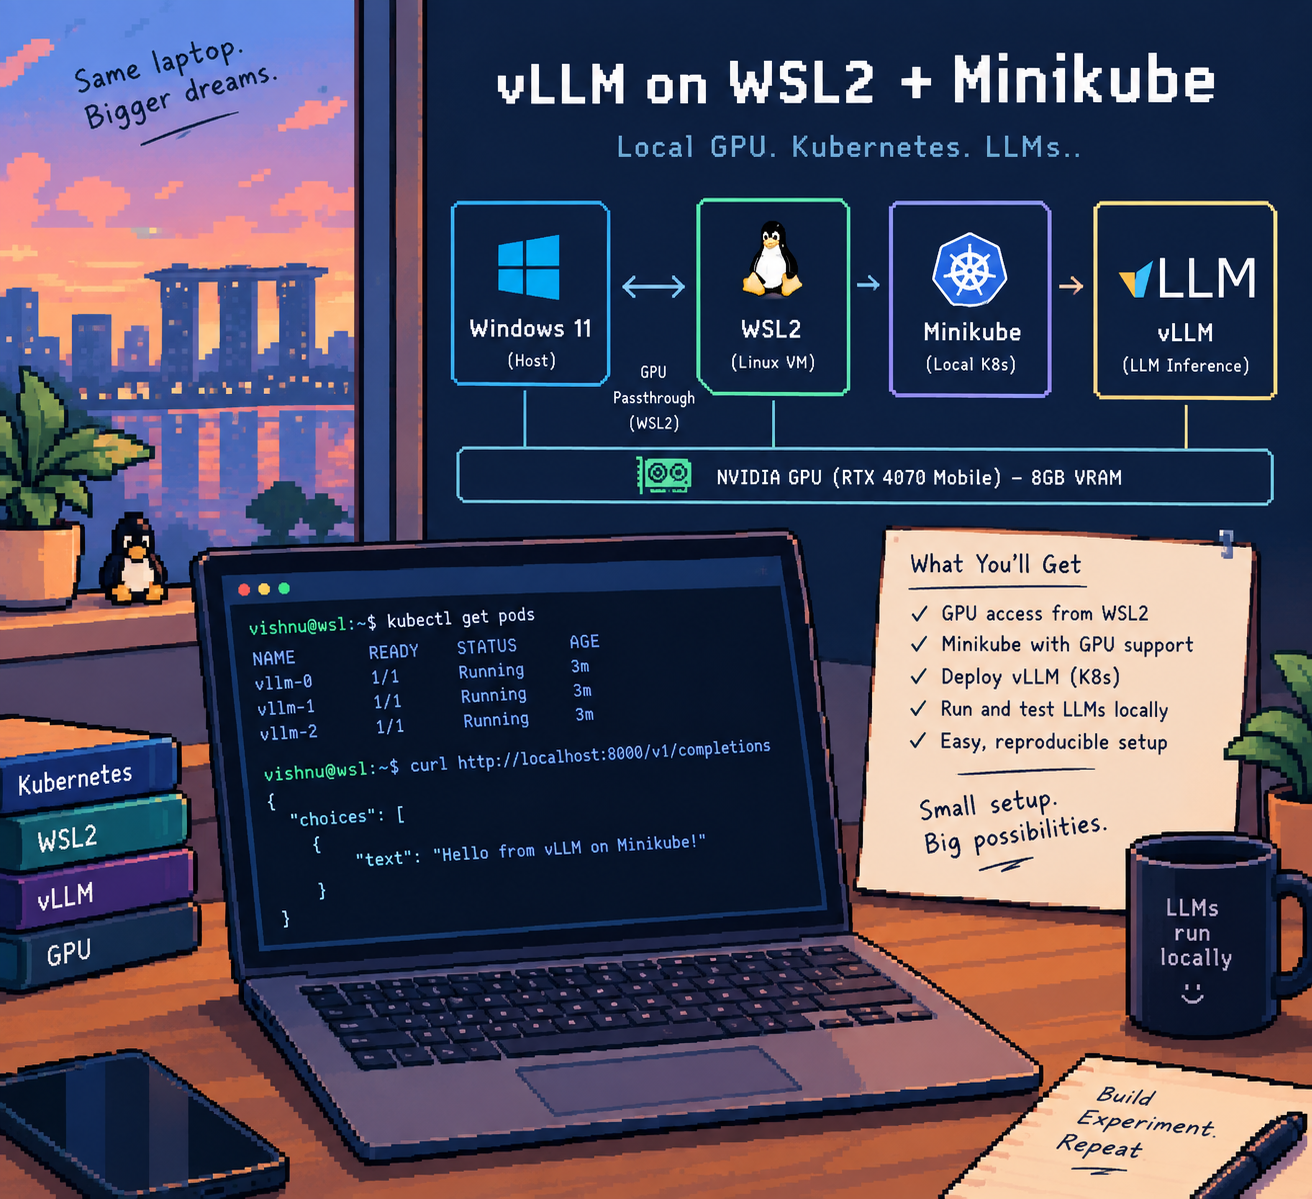
Run vLLM on Kubernetes with Minikube, WSL2 and NVIDIA GPU

Run vLLM on Kubernetes with Minikube, WSL2 and NVIDIA GPU

A practical guide to running vLLM on Kubernetes in WSL2 with Minikube, configuring NVIDIA GPU passthrough, and serving an OpenAI-compatible API.

Pixel art laptop sharing model data between host RAM and GPU memory

Running a 35B MoE Model on an 8 GB Laptop GPU: Testing FreeToken

Testing FreeToken on an RTX 4070 Laptop GPU: running Qwen 3.6 35B-A3B NVFP4 across 8 GB VRAM and 32 GB RAM with hierarchical memory offloading.