Pixel art of a local SSD transferring model tiles through a short connection into a GPU server inside a rack

Faster vLLM Cold Starts on Kubernetes: Cache the Model, Not the Download

A simple, diagram-first guide to making a new vLLM Pod ready in seconds instead of minutes: where cold-start time goes, how to cache weights on a volume, how to pre-pull the image, and which storage to pick.
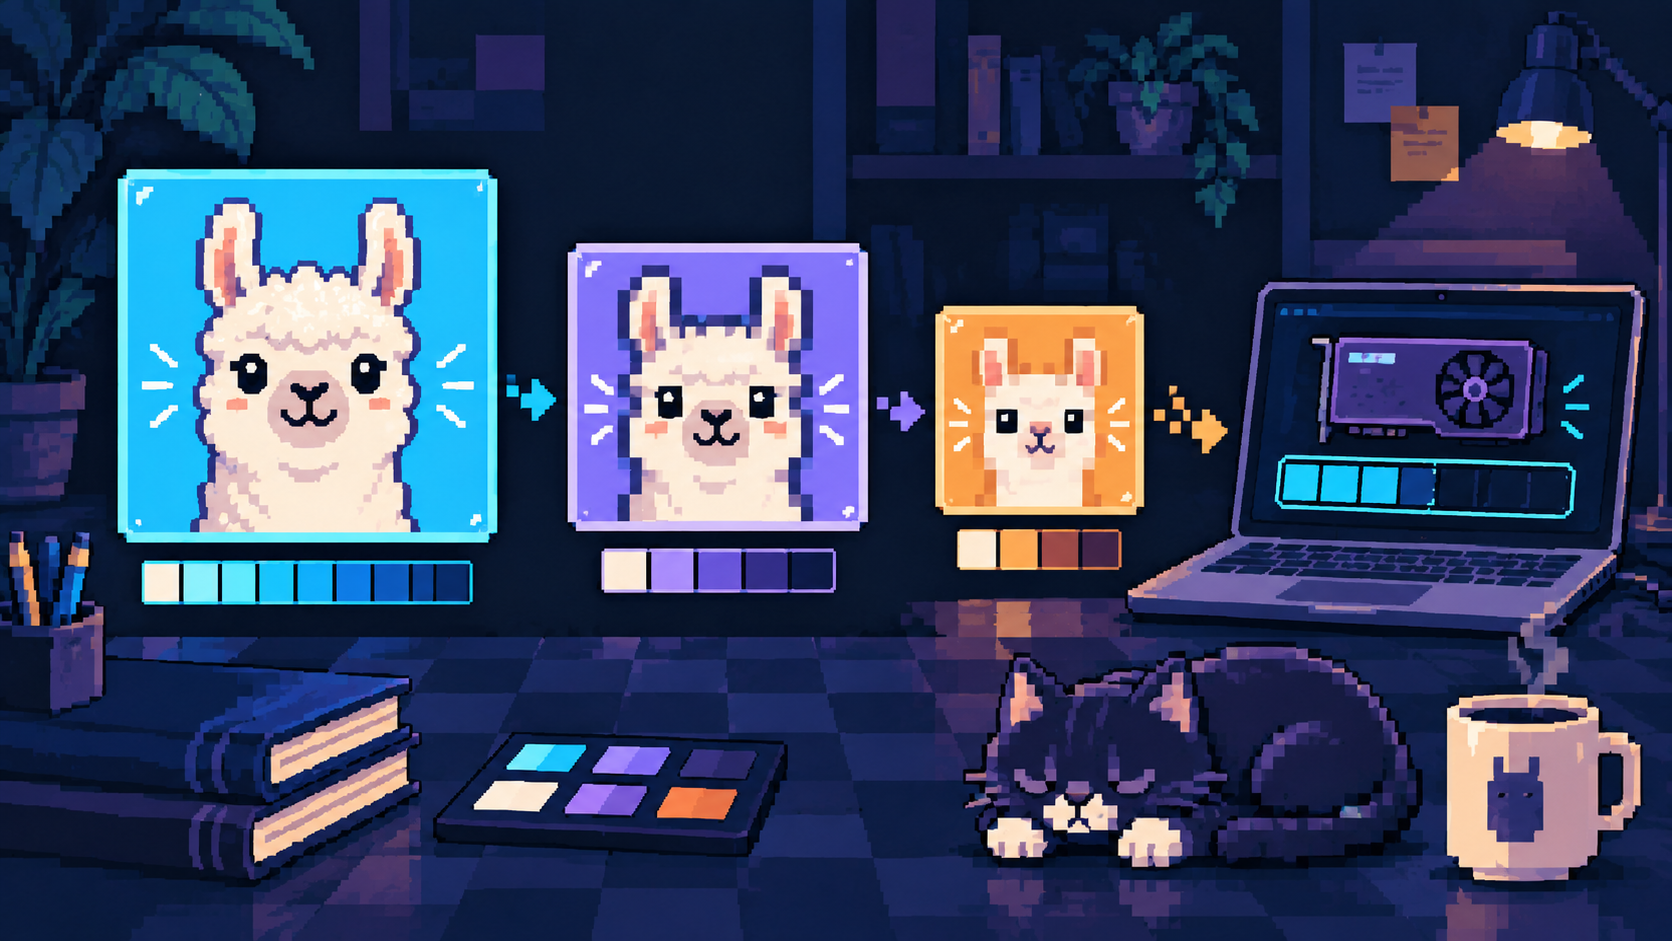
Pixel art of three llama portraits rendered at progressively coarser precision beside a compact GPU

LLM Quantization, Simply: FP16, 8-bit, 4-bit, and What Q4_K_M Means

A simple, diagram-first guide to LLM quantization: what rounding a weight actually does, how much memory each bit width saves, how to read names like Q4_K_M, AWQ, and FP8, and a toy script that shows where quality falls off.

Pixel art of a token bucket metering small requests through a shield-shaped gateway while blocking an oversized request

Rate Limiting LLM APIs: Count Tokens, Not Requests

A diagram-first guide to token budgets, fair admission, and load shedding for shared LLM APIs, with a runnable Python simulation.

Pixel art comparison showing a glowing branching Radix tree with structured bracket gates on the left and a GPU processor core packing memory pages into parallel token streams on the right

SGLang vs. vLLM: RadixAttention, Structured Outputs, and When to Pick Which

A simple, diagram-first comparison of SGLang and vLLM: how RadixAttention works, how jump-forward decoding speeds up JSON outputs, how their schedulers compare, and which engine fits your workload.

Pixel art laptop projecting a holographic GPU cluster of amber wireframe cards, with a router tower sending request cubes to them and the brightest path going to the card that holds matching cache cubes

No GPU? Simulate One: vLLM, llm-d, and 16 Fake H100s on a Laptop

A hands-on lab for learning GPU scheduling and LLM routing without a GPU: kind, fake-gpu-operator, llm-d-inference-sim, and the llm-d router, with real screenshots and benchmark numbers.

Pixel art router tower sending glowing requests to GPU racks, with the brightest path going to the rack that already holds matching cache cubes

llm-d, Simply: A Smarter Router for vLLM on Kubernetes

A practical, diagram-first guide to llm-d: why round-robin wastes GPUs, how cache-aware routing works, which well-lit path to start with, and the commands to deploy it.

Pixel art processor turning unstructured documents into parallel decision paths and probability indicators

TypeSafe’s Jev: Early Access to AI Built for Decisions

My early-access look at TypeSafe’s Jev: Noul, Choice, and Score in the playground, the coding-agent skill, and what the performance claims do and do not establish.

Pixel art cache vault reusing stored memory blocks across three GPU servers

Why LMCache Exists: Stop Making GPUs Read the Same Context Again

An example-driven guide to LMCache: repeated prefill, KV cache reuse, CPU offloading, multi-replica serving, and where caching actually helps.

Pixel art GPU server packing memory pages and serving many parallel token streams

Why vLLM Is Dominating the AI Inference Market

How PagedAttention, continuous batching, hardware portability, and an open ecosystem made vLLM the default engine for high-throughput LLM serving.