Pixel art comparison showing a glowing branching Radix tree with structured bracket gates on the left and a GPU processor core packing memory pages into parallel token streams on the right

SGLang vs. vLLM: RadixAttention, Structured Outputs, and When to Pick Which

A simple, diagram-first comparison of SGLang and vLLM: how RadixAttention works, how jump-forward decoding speeds up JSON outputs, how their schedulers compare, and which engine fits your workload.
Pixel art laptop projecting a holographic GPU cluster of amber wireframe cards, with a router tower sending request cubes to them and the brightest path going to the card that holds matching cache cubes

No GPU? Simulate One: vLLM, llm-d, and 16 Fake H100s on a Laptop

A hands-on lab for learning GPU scheduling and LLM routing without a GPU: kind, fake-gpu-operator, llm-d-inference-sim, and the llm-d router, with real screenshots and benchmark numbers.

Pixel art router tower sending glowing requests to GPU racks, with the brightest path going to the rack that already holds matching cache cubes

llm-d, Simply: A Smarter Router for vLLM on Kubernetes

A practical, diagram-first guide to llm-d: why round-robin wastes GPUs, how cache-aware routing works, which well-lit path to start with, and the commands to deploy it.

Pixel art workflow continuing through a durable history server from a crashed worker to a healthy replacement

Temporal Hands-On: Durable Execution on Kubernetes

A hands-on Temporal demo in Python: build a small order workflow, deploy it on Kubernetes, then delete the worker pods mid-execution and watch durable execution resume it.

Pixel art Kubernetes GPU cluster with two servers, cyan GPU interconnects, and a violet network fabric

Kubernetes GPU Platform Engineering: From nvidia-smi to NCCL

A simple, layered guide to GPUs on Kubernetes: GPU Operator, NUMA and PCIe, RDMA, SR-IOV and Multus, NVLink and NCCL, with a troubleshooting question for every layer.

Pixel art orchestration hub coordinating three independent Kubernetes server islands

What Is Karmada? Kubernetes Across Clusters, Explained with YAML

Karmada's CNCF graduation, its multi-cluster architecture, and practical YAML for placement, replica splitting, overrides, and failover.

Pixel art GPU server packing memory pages and serving many parallel token streams

Why vLLM Is Dominating the AI Inference Market

How PagedAttention, continuous batching, hardware portability, and an open ecosystem made vLLM the default engine for high-throughput LLM serving.

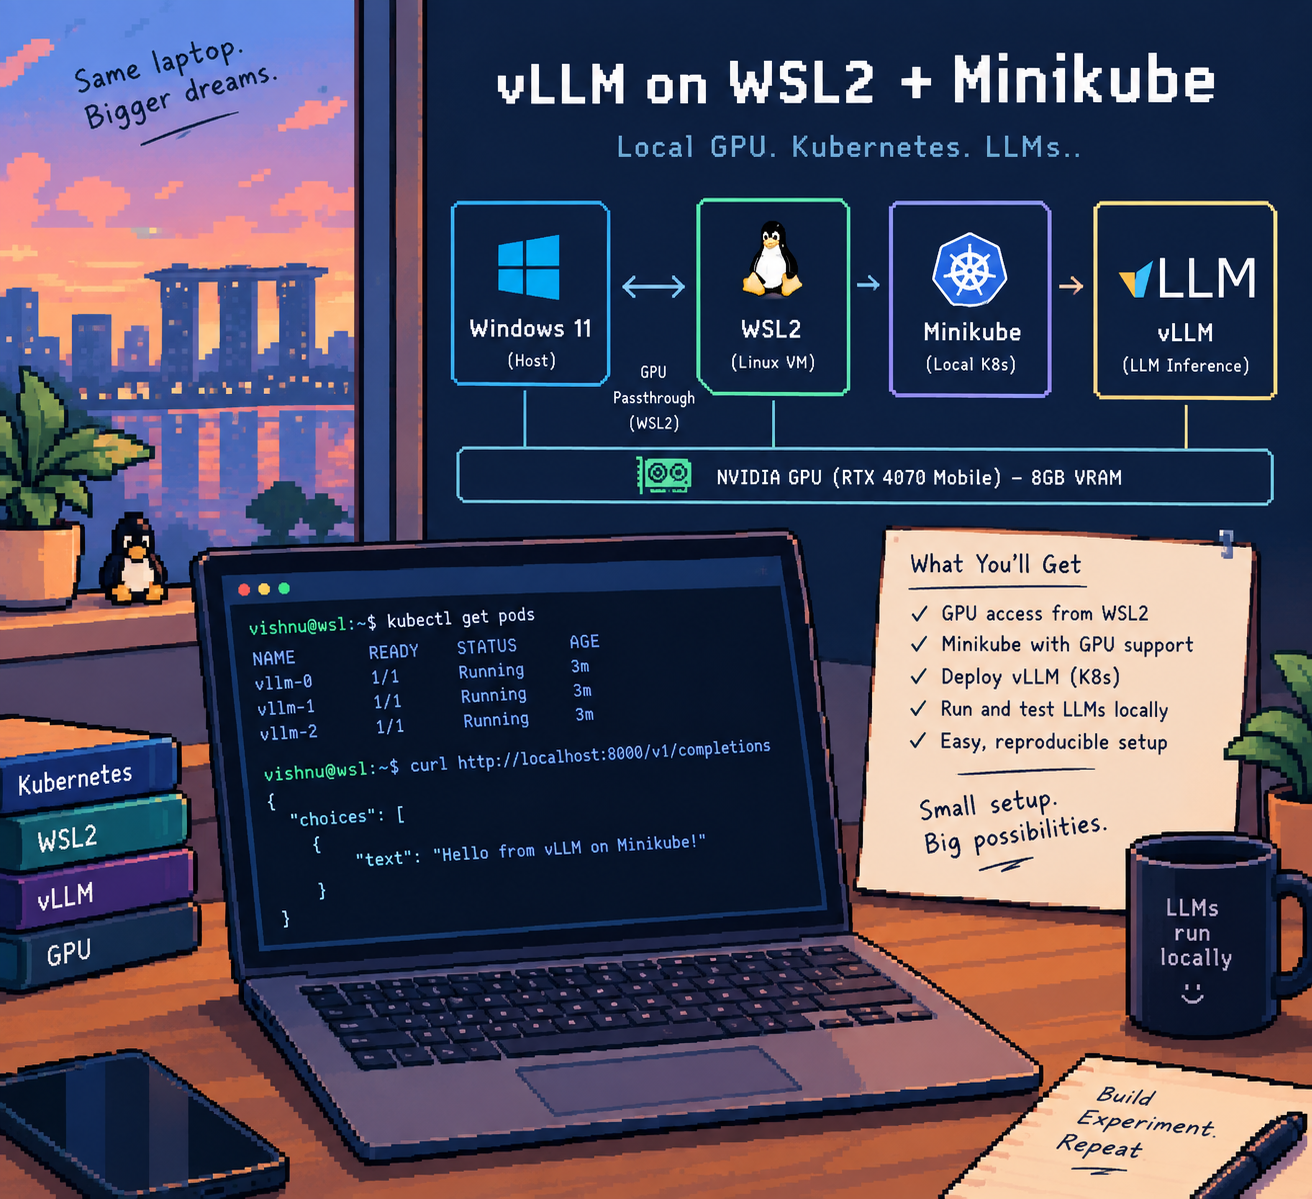
Run vLLM on Kubernetes with Minikube, WSL2 and NVIDIA GPU

Run vLLM on Kubernetes with Minikube, WSL2 and NVIDIA GPU

A practical guide to running vLLM on Kubernetes in WSL2 with Minikube, configuring NVIDIA GPU passthrough, and serving an OpenAI-compatible API.

Pixel art showing indented configuration transforming into a structured document with braces

Kubernetes is Adding a K to YAML: Why KYAML Makes Sense

Kubernetes 1.37 makes KYAML stable: how flow style eliminates silent type coercion, removes load-bearing indentation, and how to try it.

Pixel art Kubernetes wheel above connected servers against Himalayan mountains

Kubernetes v1.37: An Operator's Look at Garhwal

My notes on Kubernetes v1.37: native HPA scale-to-zero, tracking unused PVCs, ClusterTrustBundles, and etcd streaming.