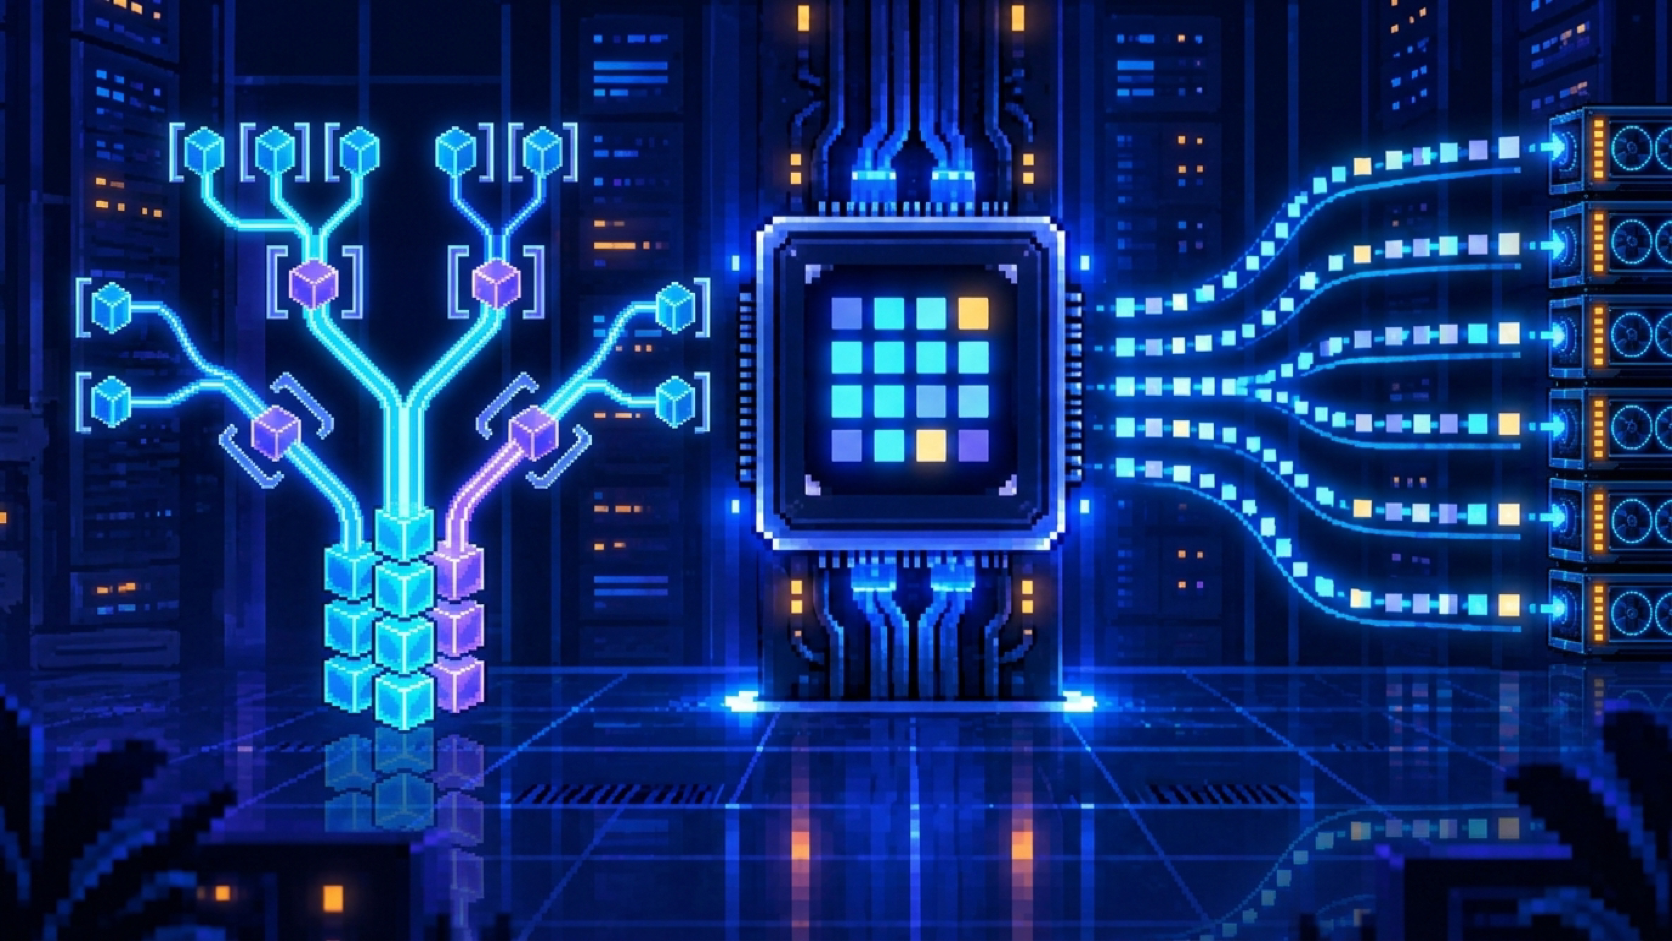
Pixel art comparison showing a glowing branching Radix tree with structured bracket gates on the left and a GPU processor core packing memory pages into parallel token streams on the right

SGLang vs. vLLM: RadixAttention, Structured Outputs, and When to Pick Which

A simple, diagram-first comparison of SGLang and vLLM: how RadixAttention works, how jump-forward decoding speeds up JSON outputs, how their schedulers compare, and which engine fits your workload.
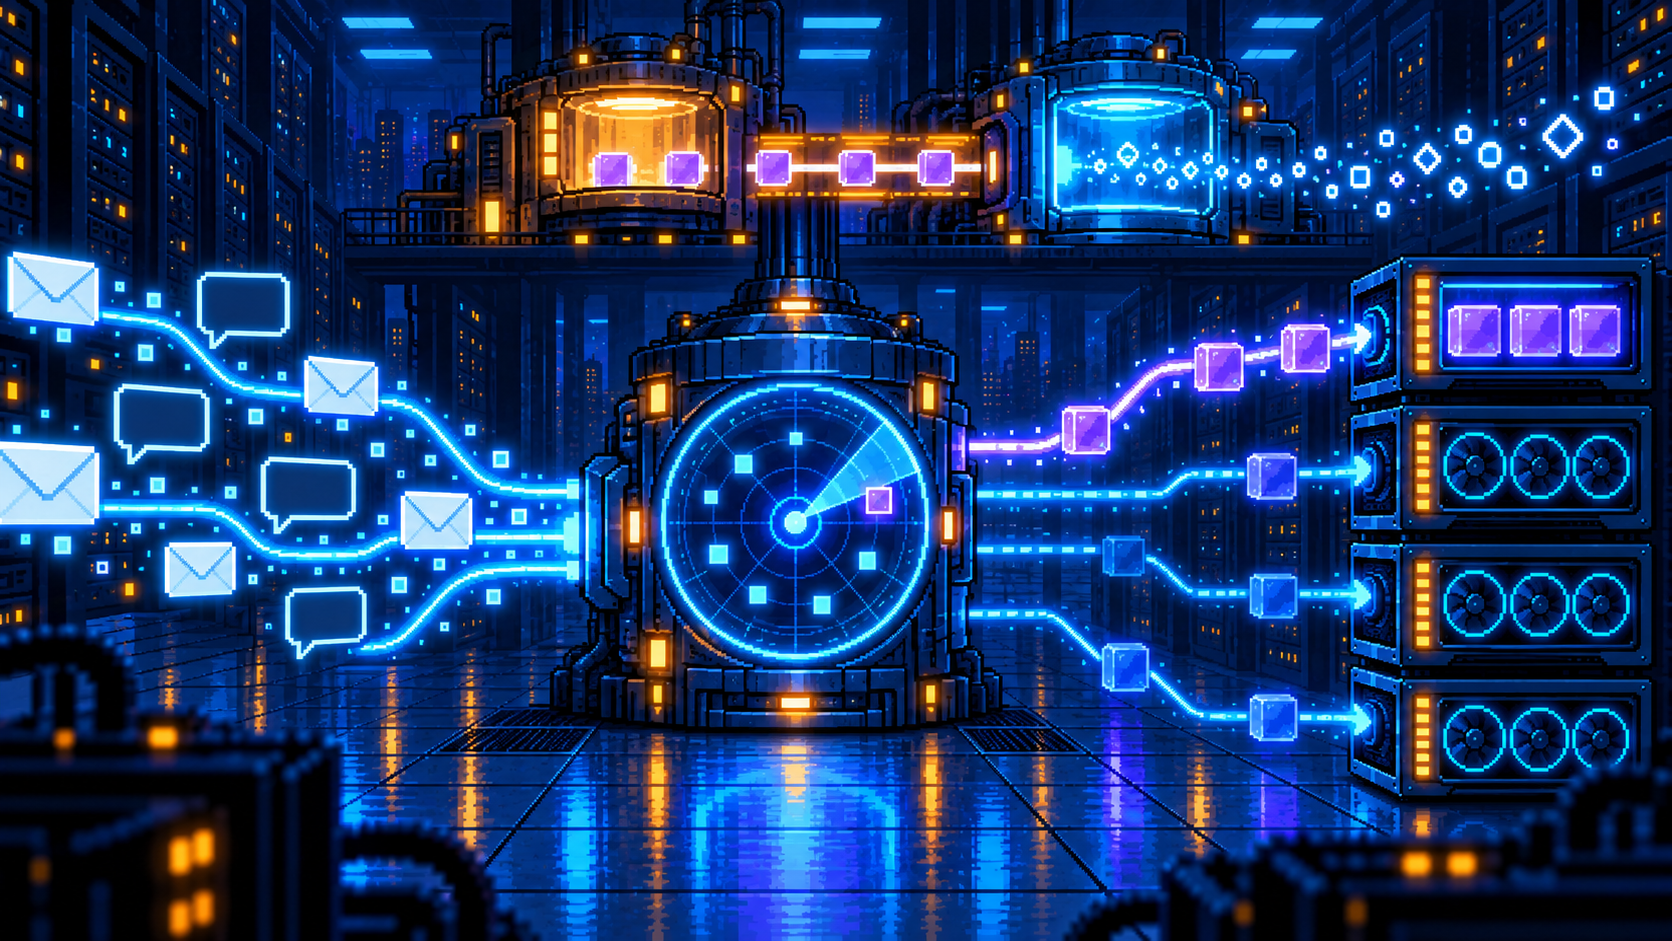
Pixel art router tower sending glowing requests to GPU racks, with the brightest path going to the rack that already holds matching cache cubes

llm-d, Simply: A Smarter Router for vLLM on Kubernetes

A practical, diagram-first guide to llm-d: why round-robin wastes GPUs, how cache-aware routing works, which well-lit path to start with, and the commands to deploy it.

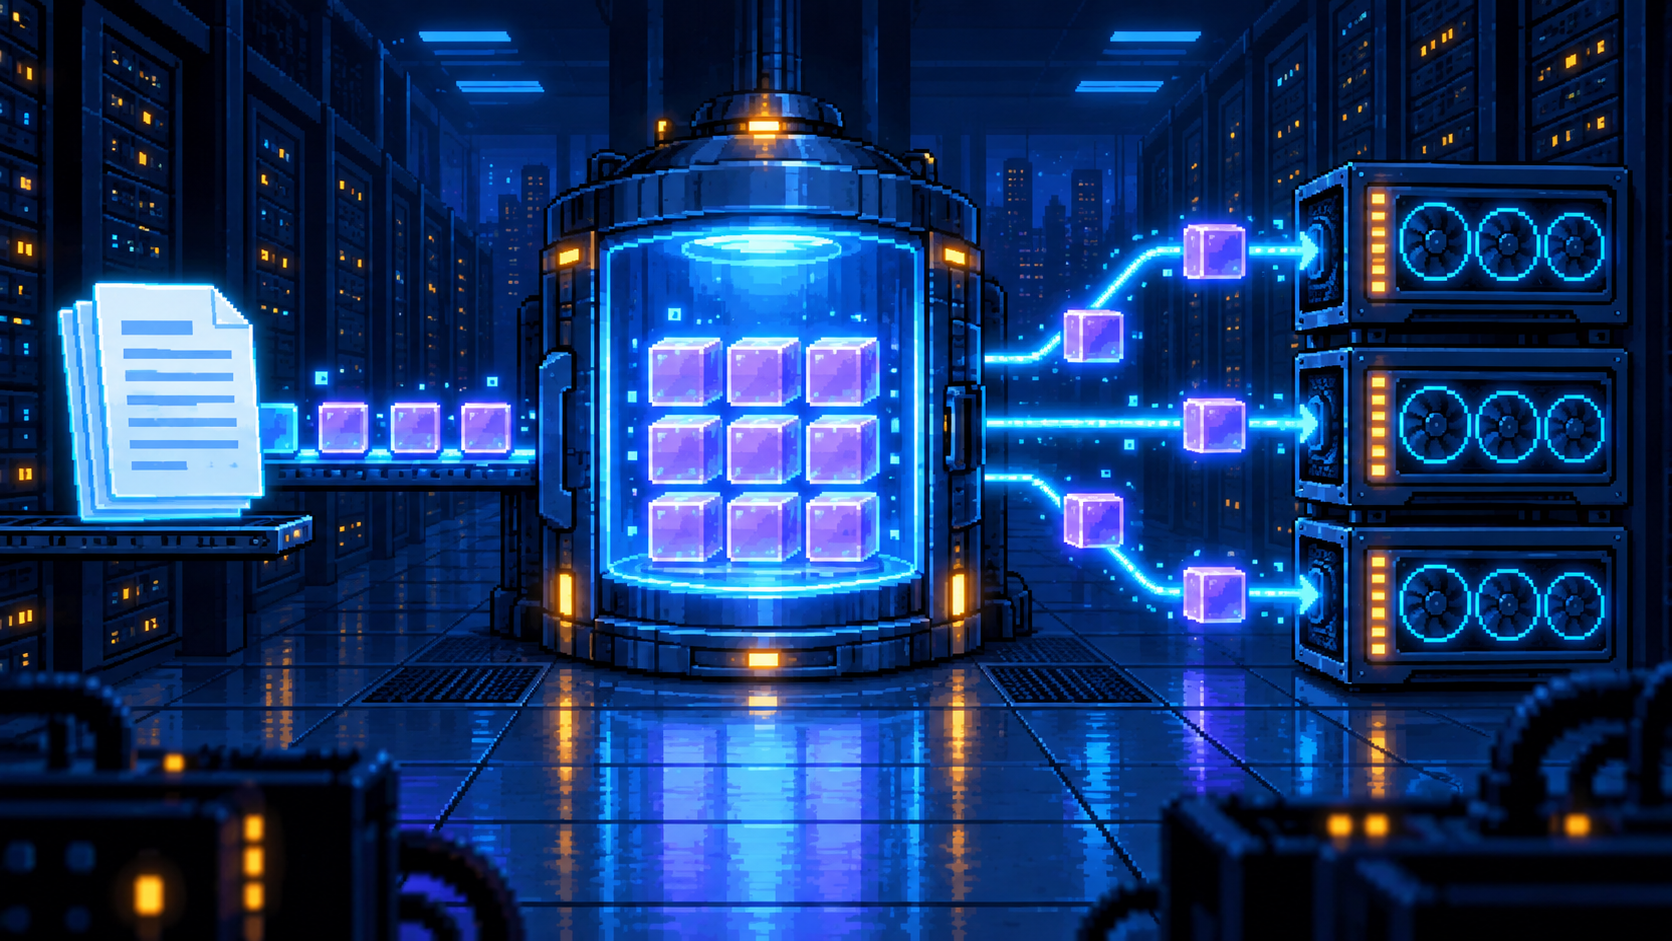
Pixel art cache vault reusing stored memory blocks across three GPU servers

Why LMCache Exists: Stop Making GPUs Read the Same Context Again

An example-driven guide to LMCache: repeated prefill, KV cache reuse, CPU offloading, multi-replica serving, and where caching actually helps.