Pixel art of three llama portraits rendered at progressively coarser precision beside a compact GPU

LLM Quantization, Simply: FP16, 8-bit, 4-bit, and What Q4_K_M Means

A simple, diagram-first guide to LLM quantization: what rounding a weight actually does, how much memory each bit width saves, how to read names like Q4_K_M, AWQ, and FP8, and a toy script that shows where quality falls off.
Pixel art laptop with a winged messenger robot exchanging requests with a gem-shaped model chip

Hermes Agent + LM Studio Bionic: Running Gemma 4 Locally

A Windows walkthrough of Hermes Agent connected to LM Studio Bionic with Gemma 4 E4B: local inference, custom endpoint settings, tool use, and the checks that confirm it works.

Pixel art MacBook connected to terminal, server, and management panels beside a llama under a night sky

oMLX vs Ollama vs vMLX vs MLX-LM: Local LLMs on Apple Silicon

My local LLM picks for Apple Silicon: oMLX first, Ollama second, vMLX third, and official MLX-LM fourth. Setup commands and the benefits of each.

Pixel art showing a question becoming tokens, passing through a neural-network chip, and emerging as an answer

What Happens When You Ask an LLM a Question

My visual notes on how LLMs work: tokens, parameters, attention, reasoning, KV cache, quantization, and serving models on GPUs.

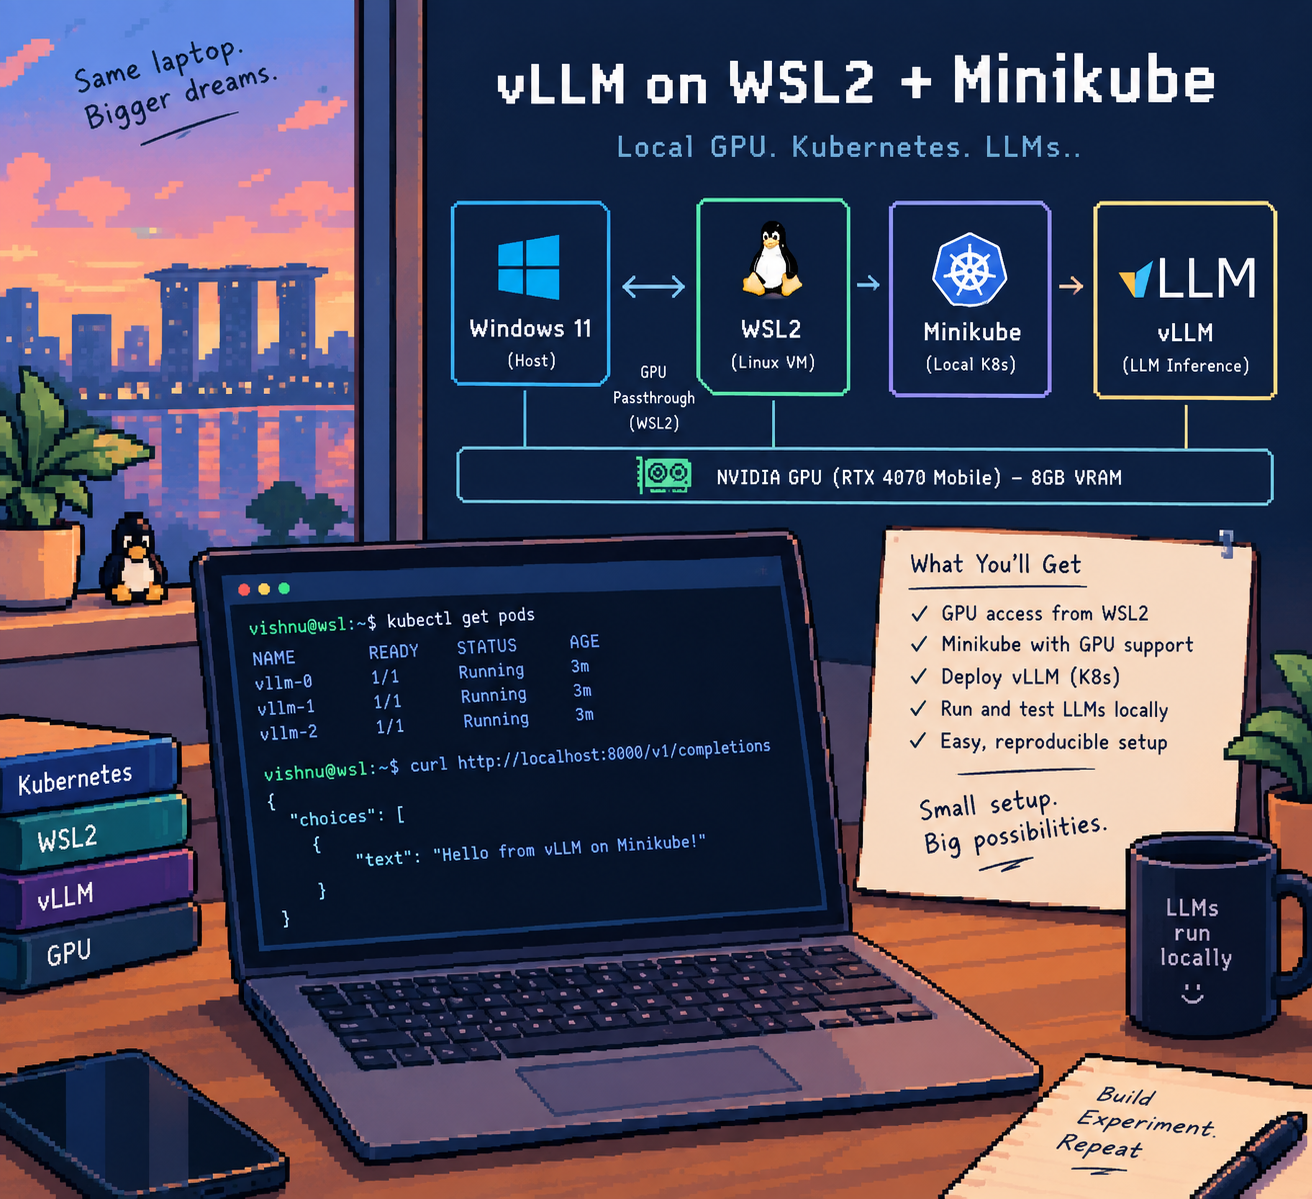
Run vLLM on Kubernetes with Minikube, WSL2 and NVIDIA GPU

Run vLLM on Kubernetes with Minikube, WSL2 and NVIDIA GPU

A practical guide to running vLLM on Kubernetes in WSL2 with Minikube, configuring NVIDIA GPU passthrough, and serving an OpenAI-compatible API.

Pixel art laptop sharing model data between host RAM and GPU memory

Running a 35B MoE Model on an 8 GB Laptop GPU: Testing FreeToken

Testing FreeToken on an RTX 4070 Laptop GPU: running Qwen 3.6 35B-A3B NVFP4 across 8 GB VRAM and 32 GB RAM with hierarchical memory offloading.

Pixel art terminal and build gear connected to a chip containing a llama

Running llama.cpp on a 32 GB MacBook Air: A Direct Comparison with Ollama

Compile llama.cpp with Metal support on Apple Silicon, serve local GGUF models, and benchmark prompt eval and generation speeds head-to-head against Ollama.

Pixel art laptop running a local llama model, with a download arrow and answer bubble

Running Ollama on a 32 GB MacBook Air: A Practical First Setup

Install Ollama, pull and run local models, and call the local API on a 32 GB Apple-silicon MacBook Air.